
The Strangler Architecture Pattern for Software Modernization

Updated: 3 hours ago
In the first installment of this three-part series, we explore the essence of the Strangler Fig pattern, its mechanics, and why it's useful for modernizing legacy systems. Through a real-world case study on modernizing a monolithic production system, we show the pattern's practical application and benefits, highlighting its pros and cons in a tangible scenario. Part three will tackle the technical challenges of running legacy systems in AI workloads.
Table of Contents
Companies that rely on legacy applications for critical business tasks need to update them to fit today’s cloud environment. Older on-premises systems often prevent organizations from using modern AI tools, auto-scaling, and real-time data pipelines.
From our experience modernizing legacy applications - most legacy apps are monolithic, making updates challenging, slow, and risky. Monolithic applications tie business functions and core logic together in one large rigid system. Over time, even small updates can cause unexpected problems across the system, making regular changes and deployments risky.
This lack of flexibility can hurt a company’s ability to compete, especially for important business operations. To stay competitive, core applications need to support quick changes, cloud connections, and real-time analytics while remaining stable.
To keep up in a fast-changing market, companies should consider breaking business functions into separate, modular parts. By adding clear interfaces to legacy functions, engineering teams can update, scale, and release features independently. This approach helps deliver ongoing business value and reduces the risk of a single point of failure.

This approach, named after the Strangler Fig tree (coined by Martin Fowler), gradually envelops a host tree and represents a gentler, iterative process, offering a distinct alternative to high-risk “Big Bang” rewrite strategies.
Rather than rewriting the massive application simultaneously, developers implement this by building new components around the edges of the old system. Minimizing technical debt, the process enables a controlled shift toward a cloud-native microservices architecture with better scalability.
Strangler Fig pattern mechanics
Here’s a step-by-step look at how the Strangler Fig pattern works:
Identify system boundaries: Begin by figuring out which parts of your current system you want to replace. This might be the whole application or just a smaller part within it.
Define thin slices: Divide the system into smaller, manageable pieces, or "thin slices." Each slice should be small enough to replace step by step, but still provide real business value. Try to make each slice independent and self-contained if you can.
Introduce an indirection layer: Add a software seam layer in your software that lets you bring in new components without users noticing any changes. This could be as simple as a switch or a more advanced routing setup, depending on your system.
Develop new components: For each slice, build a new part that does what the old one did, but with updated technology and methods. You might also need to add new features to these components.
Route traffic: When a new component is ready, set up your system so that users are directed to it through the indirection layer, instead of the old part.
Retire old components: As new parts take over, you can remove the old ones they replace. Once all the old components are gone, you can fully retire the old system.
Iterate: The Strangler Fig method is all about repeating these steps, building new parts, rerouting users, and removing old parts until the migration is complete.

To replace legacy systems, the Strangler Fig Pattern establishes a middleman, an indirection layer typically a proxy layer or façade, that sits between users and the backend systems. Such a strategy maintains backward compatibility, letting legacy system modernization proceed without disrupting active users. The transitional architecture allows for a gradual shift where traffic moves to new services while the legacy system eventually shrinks in scope.
Core Components and Strategies of the Strangler Fig Pattern
Following are building blocks that Strangler Fig operates on.
Component / Strategy | Functionality & Role | Strategic Benefit |
Strangler Fig Pattern | A software architecture strategy that incrementally replaces legacy system functionalities by building new applications around the edges of the old monolith. |
|
Proxy Layer / Façade | Acts as a "traffic cop" (often an API Gateway) that intercepts requests and routes them to either the legacy monolith or new microservices based on URI paths. |
|
Anti-Corruption Layer (ACL) | Translates data and requests between the legacy system's outdated schema and the new microservices' clean domain model. |
|
Change Data Capture (CDC) | Captures row-level changes from the legacy database's transaction log and streams them as events to the new architecture, keeping its data store in sync without modifying monolith code. | Decouples data migration from application changes
|
Distributed transactions (2PC) | Dispatches write requests to both the legacy system and new architecture simultaneously, returning only the legacy response to the user. |
|
Thin Slices (Incremental Migration) | Vertical cuts of functionality (UI, logic, data) identified by system seams and loose coupling, extracted one at a time. |
|
What is the function of the indirection layer?
Think of the proxy layer as a traffic cop. It stands between your users and your code, intercepting every request and directing it to the right destination - either the old monolith or the new service. This indirection layer hides the details of the migration, keeping the client unaware of the structural changes.
An API Gateway typically implements this logic by inspecting requests or URL paths to enforce established service boundaries. By maintaining backward compatibility, the setup ensures users don’t notice any downtime or errors throughout the modernization. The software architecture relies on this component to safely divert traffic incrementally without operational disruption.
What is the anti-corruption layer?
The Anti-Corruption Layer (ACL) acts like a translator at the border, converting the legacy system dialect into the clean language of your new microservices.
It protects the new architecture by translating data and requests between the legacy system's outdated schema and the new domain model. Such a translation mechanism guarantees domain isolation by converting legacy formats into clean structures on the fly, preventing technical debt from leaking into the new environment.
You need to isolate the new model to apply domain-driven design principles based on current business needs, rather than inheriting the rigid schemas and confusing naming conventions of the legacy system of record.
Without this layer, new services risk adopting obscure logic or column names from the monolithic application, compromising the clean architecture.
Incremental Migration How-To's
Migrating with Strangler Fig is a loop: identify → transform → eliminate. This iterative approach continues until the legacy system modernization is complete.
System seams and thin slices identification
Architects identify candidates for incremental migration by locating system seams where the code exhibits loose coupling - areas where components aren’t tightly dependent on each other. These seams act as natural service boundaries that allow for the extraction of components without destabilizing the core monolithic application.
A thin slice includes the user interface, logic, and data required for a specific task. Common starting points include a self-contained user authentication module or a specific reporting feature.
We recommend starting with such "easy wins" to help the team get comfortable with the new workflow. Selecting these isolated components first allows teams to address technical debt and validate the new microservices architecture before tackling complex core logic. Isolating components keeps the migration manageable and provides quick feedback.
Ensuring integrity and validity of new implementation
Thorough testing helps make sure the new system works as expected and keeps the rest of the system stable. In a Strangler Fig migration, focus integration tests on the points where the API Gateway, Anti-Corruption Layer (ACL), and the old monolith meet.
These tests confirm the gateway routes traffic correctly based on user groups or path rules, and that the ACL correctly transforms new domain events and data into the old database formats without losing data or causing delays.
By running automated integration tests on these connections while traffic shifts, engineering teams can confirm that data stays consistent and the system remains reliable, so customers do not notice problems during the gradual migration.
Routing traffic between the old and new services
Traffic routing relies on the proxy layer acting as a façade. This indirection layer uses URI paths, headers, or cookies to split traffic between the monolithic application and the new modernized application. You update the configuration as you deploy new services, so the gateway reflects the current service boundaries.
Fallback mechanisms default to the legacy system for any undefined routes, maintaining backward compatibility within the transitional architecture. For example, traffic for /api/v2/inventory routes to the new cloud-native service, while /api/v1/inventory stays with the monolith. Granular control makes the migration safer.
Managing data synchronization during incremental migration
In general modernization is used as an opportunity to refactor the data model or to denormalize for performance, or to split a monolithic database by domain. In such cases, the new system will have different data store, separate from the legacy’s database. This requires a strategy to keep data consistent between old and new during the migration. Gradually transfer relevant data from the legacy DB to the new system DB as each feature is strangled, rather than a massive one-time migration.
When dealing with divergent data models during system modernization, synchronizing data across legacy and new system becomes one of the hardest challenges. Depending on your constraints like: real-time needs latency tolerance, consistency guarantees, infrastructure limitations, different architectural strategies may be more appropriate.
There are many approaches to the problem:
Change data capture (CDC)
Distributed transactions (2PC)
Event publishing
Shadow writes
Transition journey overview
Modernization with divergent data models typically unfolds in three major phases, regardless of which synchronization strategy you choose:
Phase # | Details |
|---|---|
Phase 0. Bootstrapping | Data pipeline is used to populate the new system’s database with a clean snapshot of legacy data. |
Phase 1. Coexistence with Sync Strategy Selection |
ACLs and Event Adapters handle translation and mapping between differing data models |
Phase 2. Legacy DB Detachment |
|
Phase 3. Full Legacy Retirement |
|
Let's review two strategies, such as CDC and 2PC for managing data sycnhronization between two systems.
Strategy 1: CDC + Stream + Event Adapter
Best fits: Non-invasive data sync when legacy systems can’t emit events.
Legacy and New systems both write to their own databases.
CDC (Change Data Capture) tools capture DB changes and publish them to a stream.
Event Adapters consume those events and convert them to the new system’s data model.
ACLs (Anti-Corruption Layers) manage direct service interactions between systems, translating models and API calls as needed.
Pros:
No need to change legacy code.
Works in near real-time.
Scales well for high-throughput systems.
Cons:
Eventual consistency.
CDC pipelines may lag during heavy write loads or batch jobs

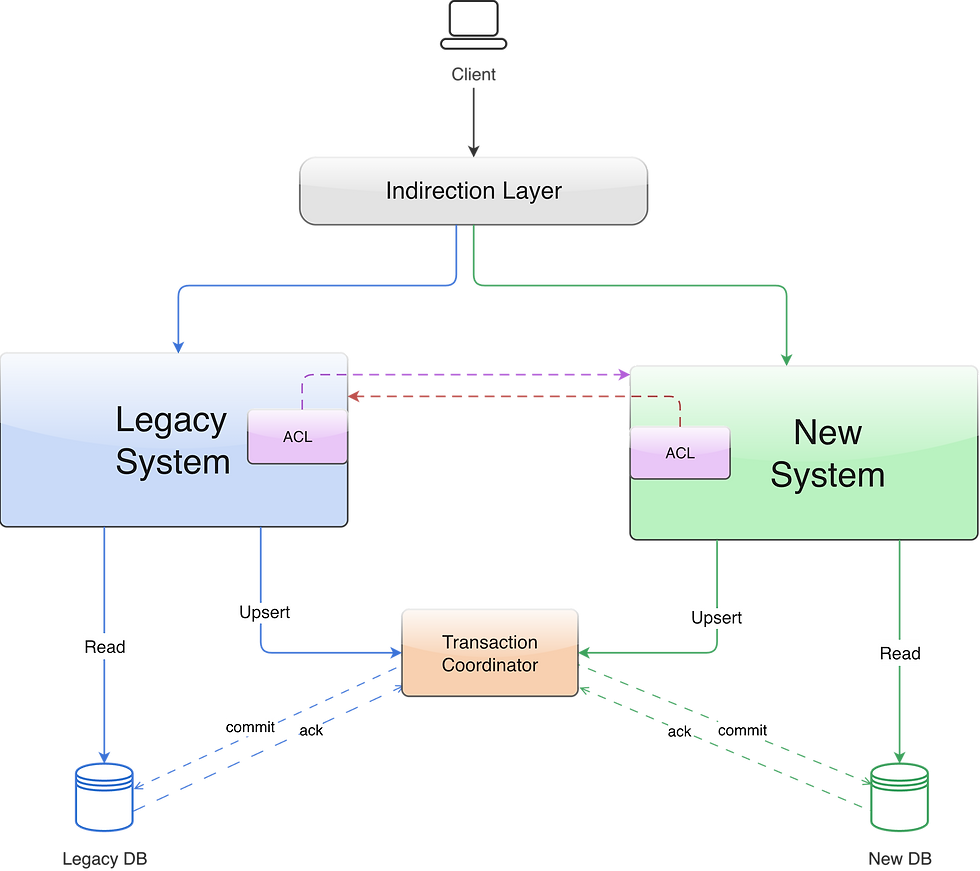
Strategy 2: Distributed Transactions (2 Phase Commit, 2PC)
Best fits: Highly critical systems requiring strong consistency.
A Transaction Manager coordinates operations across Legacy DB and New DB.
Each system receives an upsert call, holds the transaction, and only commits after receiving an “OK to commit” signal.
Both systems either commit or rollback, maintaining atomicity.
Pros:
Strong consistency.
Cons:
Higher latency.
Risk of locks or deadlocks under load.
Not suitable for high-frequency or distributed architectures.
Decommissioning the legacy system
Only decommission a feature when it is fully replicated in the strangler application and data synchronization is complete. Wait for monitoring tools to confirm that zero traffic is reaching the legacy component before taking any action. This verification step confirms the new service functions as the definitive system of record.
Teams remove dead code and unused database tables from the monolithic application once the transitional architecture directs all requests to the new environment. Eliminating these artifacts reduces technical debt and minimizes maintenance overhead. The final cutover happens when the legacy system is entirely empty or reduced to a negligible size.
How does incremental migration mitigate technical risk?
Incremental migration reduces technical risk by breaking changes into small, manageable pieces. This way, if something goes wrong, the problem stays within one part of the system. Limiting changes to a single service keeps errors from affecting the whole application. Updating one function at a time helps teams spot issues early and fix problems quickly. Debugging is also simpler because it is easier to find and fix bugs in a microservices setup than in a complex legacy system.
Immediate fallback options help keep systems running smoothly. For instance, if a migrated Billing service fails, the system can quickly switch back to proxying the legacy part. This keeps the business running and lets teams test each update carefully. Fast feedback helps developers pay down technical debt step by step, avoiding the big problems that come with rewriting everything at once. This approach makes updating old systems more stable and predictable.
What challenges and risks are associated with this pattern?
While the Strangler Fig Pattern offers a safer alternative to a total rewrite, it comes with significant architectural trade-offs. According to Plexteq experience here are the most often root causes that are causing migration failures
Failure cause | Symptom | Explanation |
|---|---|---|
Started at UI layer | New UI tightly coupled to legacy backend | Replacing the front end first delivers a visible win but leaves the legacy backend's data model and business rules untouched. The new UI ends up calling legacy APIs directly and absorbing their quirks, creating a "facade without substance." Each later backend change then forces UI rework, so the hardest part of the migration is only deferred and made more expensive. |
No stable semantic boundary | Endless scope creep ("just one more field") | The prolonged duration of the migration process frequently leads to "migration fatigue." Because risk mitigation relies on small, iterative steps, the complete replacement of a large system can take years. |
Treated legacy DB as immutable | Dual-write problems, data sync failures | Keeping the legacy database and new storage solutions consistent requires sophisticated replication strategies that can be difficult to implement correctly. Any failure in this area leads to data corruption, undermining the reliability of the legacy system modernization. |
Underestimated observability | Can't debug distributed system | A request that used to run inside one process now crosses the proxy, both systems, and the event stream. Without distributed tracing, correlation IDs, and centralized logging in place from day one, teams cannot tell which side handled a request or where it failed. Incidents take longer to diagnose than they did in the monolith, which erodes confidence in the new system. |
Cultural resistance (no DevOps) | Teams refuse to own new services | Incremental migration assumes teams can build, deploy, and operate services independently. Where delivery still relies on handoffs to a separate operations group, nobody takes end-to-end ownership of the new services. They become orphaned or pile up behind the legacy release process, and the organization ends up running two systems with the operating model of one. |
What is your readiness score?
Rate each item 0-10 to assess your rediness to modernize your system:
Category | Question | Your Score |
|---|---|---|
Boundaries | We have identified clear, stable bounded contexts (DDD) | __/10 |
Testing | Legacy component has >70% automated test coverage | __/10 |
Monitoring | We have distributed tracing + centralized logging ready | __/10 |
Data | We have a documented data ownership + sync strategy | __/10 |
Team | Team has distributed systems expertise (Kafka, CDC, sagas) | __/10 |
Budget | Stakeholders approved 12-18 month dual-operations cost | __/10 |
Culture | Teams willing to own full lifecycle (DevOps) | __/10 |
Total: __/70
60-70: Greenlight: proceed with confidence
50-59: Viable: address gaps in parallel
40-49: Risky: invest in prerequisites first
<40: Not ready: stay monolithic or modular monolith
When should you use the Strangler Fig Pattern?
The Strangler Fig Pattern works best for large, complex systems and monolithic applications where rewriting everything at once is too risky. It is designed to modernize legacy systems that support critical business functions and cannot afford downtime.
Organizations use this pattern to move gradually to a cloud-native microservices setup while keeping development going. It is especially useful for systems with significant technical debt, where the codebase has become too hard to fully understand.
For small, simple applications, using a transitional architecture usually adds unnecessary overhead.
This pattern is especially important for modernizing mainframes or breaking up large enterprise ERP systems, where moving in small steps is the only practical option.
The main reason to use this approach is to reduce risk, especially when a full rewrite could fail and cost more than running old and new systems side by side.
Scalability needs can also lead teams to choose this pattern, since it lets them pull out and improve specific bottlenecks on their own.

FAQ
What is the strangler fig pattern?
It is an incremental modernization approach: you build new services around a legacy system, route traffic to them piece by piece, and retire the old code once nothing depends on it. While pattern is usually pitched as gradual and low-risk, many attempts stall within the first 2-4 months without replacing a single monolith component.
Why do strangler fig migrations fail early?
We have seen a number failure modes: starting at the UI layer, lacking a stable semantic boundary, treating the legacy database as untouchable, underestimating observability, and cultural resistance to teams owning new services.
When is a big bang rewrite the better choice?
When the legacy system is a black box with no documentation, no remaining experts, and no module boundaries to cut along, or when the business can tolerate a maintenance freeze. Strangler fits better when logic is modular, the team knows the legacy code, and downtime is not acceptable.
What should be in place before starting?
Legacy test coverage, a stable domain boundary, stakeholder buy-in for dual operations, a single accountable owner, monitoring, a data ownership plan, a reconciliation strategy, and an instant rollback switch. We also suggest assessing via seven-item readiness score mentioned in the blog post.


